Jev vs. Claude vs. local ML ticket classification
posted
Heard about Jev from TypeSafe AI? It’s a “System One” model: you give it a bag of words, and it returns one of your options with probabilities. Last night, I thought of a use-case around support tickets.
I support HR and ticket deflection1 is a big deal. Fast and accurate responses create delightful employee experiences.
- System One prompt: “Is {input} about {Benefits | Payroll | Recruiting | IT}.”
- Generative AI prompt: “Find all the help articles related to {input}.”
A Jev-like model wouldn’t be great at summarizing or retrieving documents from a large database. It could be good at routing and assigning tickets though.`
Vibe-coded demo
I built a demo that races five classifier methods through the same tickets and shows time, cost, and accuracy live. The code is on GitHub: sglmr/jev-bilingual-ticket-classification.
A live 200-ticket race with real API calls. Classic ML (0.14s), Jev (4.9s), Embeddings ML (7.1s), Haiku (25s) and Sonnet (45s).
The data
ale-dp/bilingual-ticket-classification has over seven thousand English and German support tickets. Each ticket has three labels:
- Queue (10): Billing and Payments, Customer Service, General Inquiry, Human Resources, IT Support, Product Support, Returns and Exchanges, Sales and Pre-Sales, Service Outages and Maintenance, Technical Support.
- Type (4): Incident (something broke), Problem (a recurring issue with an unknown cause), Request (asking for information or a service), Change (asking to change something).
- Language (2): English or German.
The data isn’t perfect. My agent suggested there may be some incorrect language labels and queue labels in the dataset.
The contestants
| Lane | What it is | Trained on |
|---|---|---|
| Jev | one API call per ticket, three “choice” questions | nothing (zero-shot) |
| Claude Haiku | claude-haiku-5-5, forced tool call with enum fields |
nothing (zero-shot) |
| Claude Sonnet | claude-sonnet-5-5, automatic tool choice |
nothing (zero-shot) |
| Classic ML (local) | TF-IDF word counts + logistic regression, local | 6k+ labeled tickets |
| Embeddings ML (local) | multilingual MiniLM embeddings + logistic regression, local | 6k+ labeled tickets |
The local models set a baseline example without the AI API bill. They trained on a random 80% of the tickets. The remaining 20% of the tickets got reserved for the race.
Run 1: 500 tickets
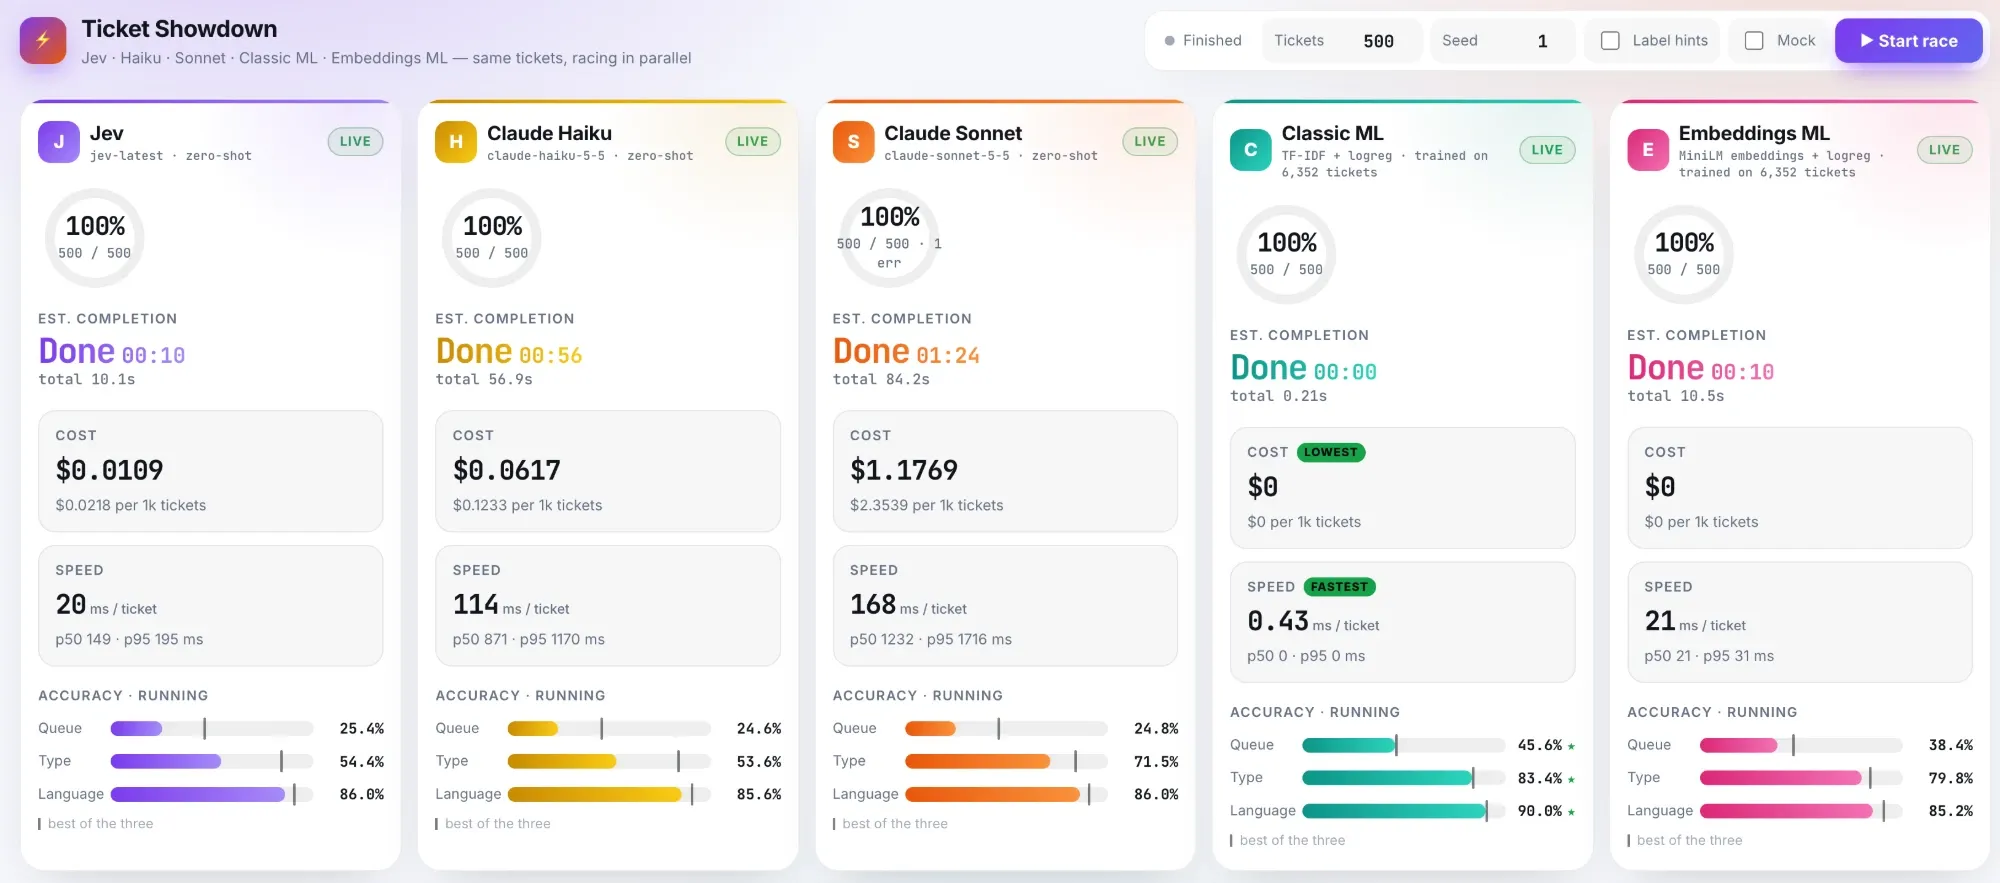
| Time | Cost | Queue | Type | Language | |
|---|---|---|---|---|---|
| Jev | 10.1s | $0.0109 | 25.4% | 54.4% | 86.0% |
| Claude Haiku | 56.9s | $0.0617 | 24.6% | 53.6% | 85.6% |
| Claude Sonnet | 84.2s | $1.1769 | 24.8% | 71.5% | 86.0% |
| Classic ML | 0.21s | $0 | 45.6% | 83.4% | 90.0% |
| Embeddings ML | 10.5s | $0 | 38.4% | 79.8% | 85.2% |
- Jev matched Haiku’s accuracy and was about 5.6x faster and 5.7x cheaper.
- Only Sonnet did well on type (71.5% vs 54%). But cost 108x more than Jev.
- Queue was hard for every model. AI models hovered around 25% and local models got up to 46%.
- The 0.2-second local TF-IDF model won every column, for free.
Run 2: with label hints
This time, the AI models got label hints for the same 500 tickets. (Local models ignore hints.)
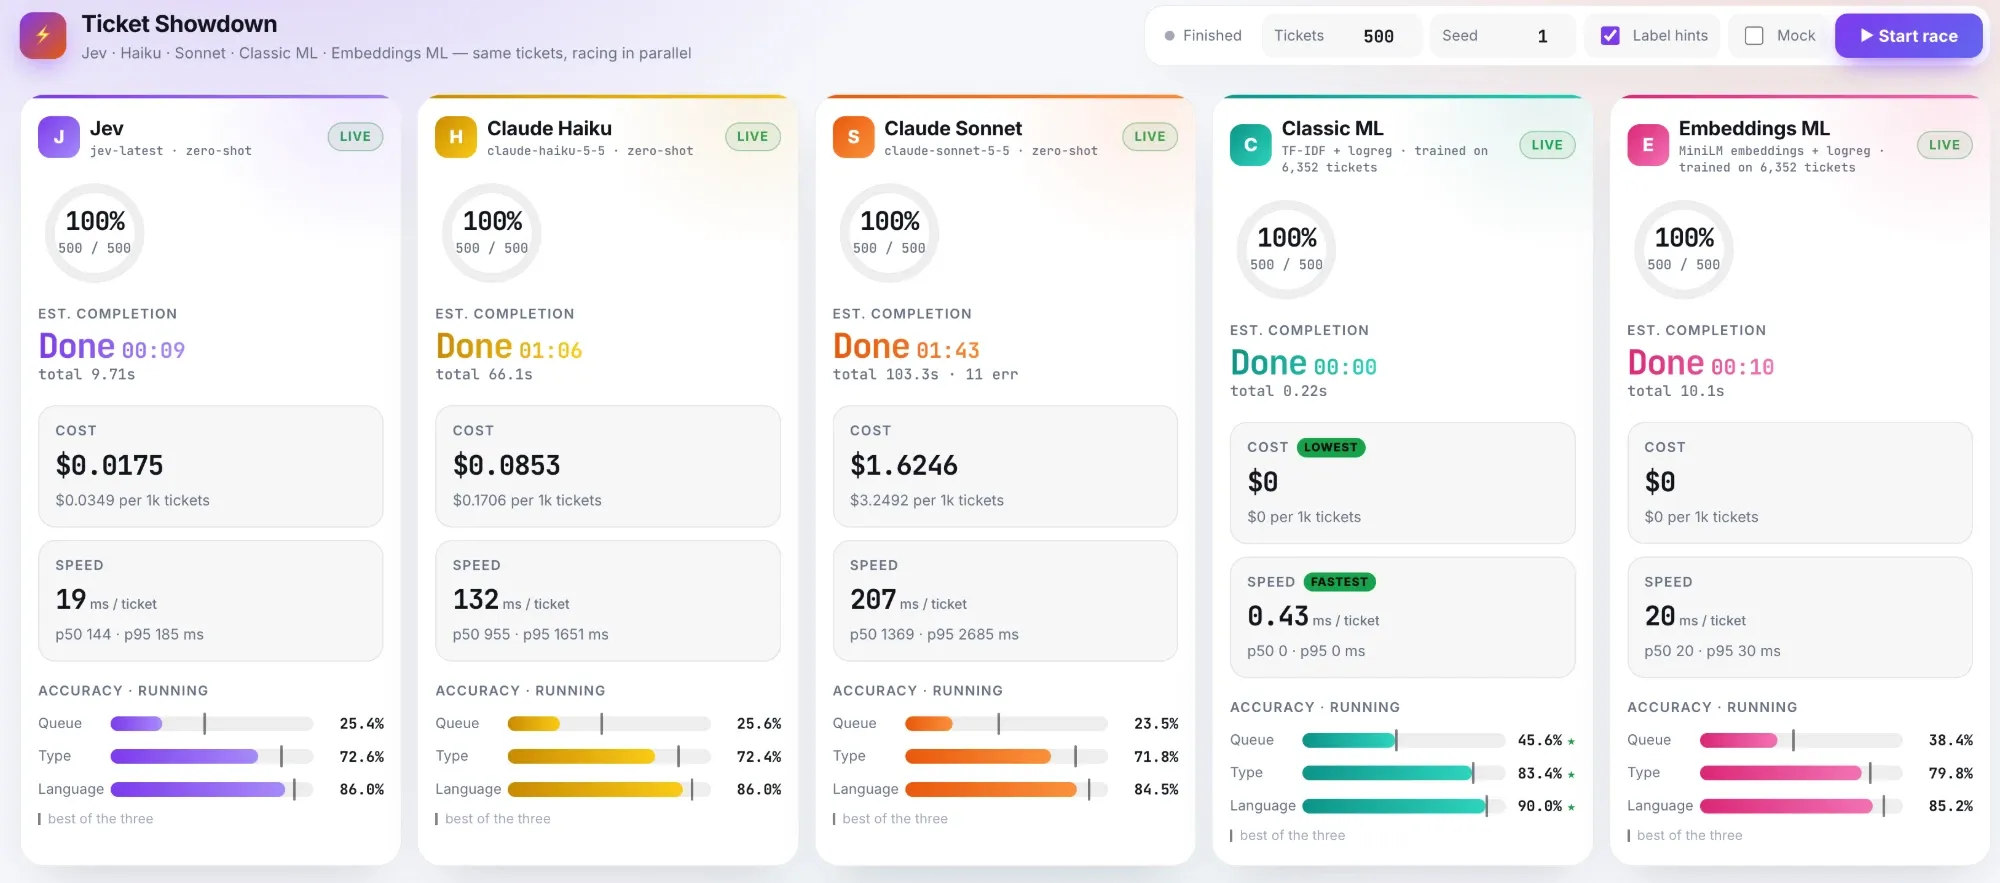
| Time | Cost | Queue | Type | Language | |
|---|---|---|---|---|---|
| Jev | 9.7s | $0.0175 | 25.4% | 72.6% | 86.0% |
| Claude Haiku | 66.1s | $0.0853 | 25.6% | 72.4% | 86.0% |
| Claude Sonnet | 103.3s | $1.6246 | 23.5% | 71.8% | 84.5% |
| Classic ML | 0.22s | $0 | 45.6% | 83.4% | 90.0% |
| Embeddings ML | 10.1s | $0 | 38.4% | 79.8% | 85.2% |
- The hints closed the type gap. Jev and Haiku each gained about 18 points rivaled Sonnet, which didn’t move. (Sonnet’s first round lead could have been knowing what “Incident” versus “Problem” meant.)
- The hints don’t always help. They did nothing for queue.
- Hints cost 38 to 60% more in tokens. Jev still did 500 tickets for $0.0175, about 93x cheaper than Sonnet at the same type accuracy.
Summary
- If you have labeled data, use it. A logistic regression trained in seconds crushed every LLM-style model here.
- Without labeled data, Jev is efficient. As accurate as Haiku without hints. And as accurate as Sonnet with hints. At a fraction of the cost and latency.
- Tell the agents what the labels mean. Jev did 18 points better on one of the 3 classifications with a 1 sentence label definition.
- Check labels before blaming model. Two of the three fields appear to have a ceiling set by incorrect labels in the dataset.
Try it for yourself
Everything’s in this repo. You’ll need uv, the dataset (one curl command in the README) and API keys for Anthropic and TypeSafe.
Footnotes
-
Ticket deflection is resolving customer or IT support user issues with automated tools before it gets to a human agent. ↩